
Most of what we know about creating content for AI Search tells us what that content looks like. It advises you to create content that is citable, extractable, and organized. However, it doesn’t tell you how to transform the brief you give a writer into something that meets those requirements or what the differences are at the individual sentence level with regard to whether the LLM cites or skips content based upon those characteristics.
This article is at the brief level. This article is written for the professionals who create content daily – Content Heads, Senior Editors, Content Strategists and the writers working beneath them. After you read this article, you’ll be able to take tomorrow’s content brief and specifically change it so as to increase the likelihood that the piece cited by the AI, while maintaining its quality for human readers.
Throughout the article, my argument remains consistent with the argument I’ve presented in each of the previous articles within this series. In most cases, AI-citable content and high-quality human-readable content do not exist in opposition. They are typically the same type of content. Precise (and therefore) direct language is both excellent writing and the type of language that an LLM cites. Vague marketing-heavy preambulatory language is poor writing and is likewise avoided by an LLM.
The approaches described in this article were derived from Infidigit’s experiences providing content for over 200+ brands as well as from structural changes to the content delivery process which produced measurable increases in citations in our AIO work. When referencing a client experience, I provide a hyperlink to the publicly available case study.
Why the Brief Level Is Where AI Citability Is Won or Lost
Strategy documents define which aspects are to be optimized. Briefs are used to define which aspects will get described. The difference between an AIO (Artificial Intelligence Optimization) strategy and how well AIO content performs generally lies at the brief level, and rarely at the strategy level.
I’ve reviewed many content briefs created by enterprise marketing departments that developed and published first-rate AIO strategies in separate decks but did not reflect their respective AIO strategies within the briefs they sent to writers. These included briefs that stated “target keyword”, “word count”, “meta description”, and “include these three internal links”. Writers then wrote keyword-optimized content. That keyword-optimized content performed in traditional search rankings; however, it was not cited by any AI systems. The AIO strategy itself was correct. The brief never changed.
Semrush’s AI Visibility Index 2026 found that organizational integration (integration of all processes across the organization) was the most significant factor associated with the ability of organizations to perform on AI Search Engines. Specifically, 81% of teams with complete integration of SEO and AI Search Engine execution reported increased traffic or lead generation through use of AI Search Platforms when compared to only 36% of teams with completely separate workflows. Wherever this integration occurs is where the unified brief exists, whether it is through two separate documents (one for SEO and one for AIO) or a single document outlining the requirements for a single piece of content.
A unified brief is defined operationally as one that outlines the requirements for both keywords for a particular piece of content and also defines requirements for citation of that content by AI Systems. In contrast, two separate documents, one for SEO and one for AIO would represent a workflow that has no integration, and therefore will likely produce less than ideal results.
This article provides definitions and example descriptions of what a unified brief might look like in practice, and identifies areas where changes may need to occur to create a unified brief.
What Is the First 200 Words Rule and Why Does It Determine AI Citability?
AI retrieval systems determine what information is relevant and authoritative based on a pieces opening. The thought process is analogous to how people decide whether or not to continue reading; if the first paragraph of an article does not provide a clear and direct answer to the question posed by the title, the AI will move on to the next possible source.
Most enterprise content begins with introductory paragraphs (the preamble), defines the context for the content, and may define the topic. The majority of these types of articles do not have a specific, verifiable statement within those first 200 words that clearly responds to the query described in the title. That is the change needed here.
Rule: The first answer needs to be found in the first line of the content body, rather than in the third line. The first sentence of this content body should clearly address the implied question as stated in the title. All other elements will follow that.
| Generic preamble: not AI-citable
AI-driven search is transforming the way customers discover brands online. In today’s rapidly evolving digital landscape, businesses need to adapt their content strategies to remain visible across AI platforms. This article explores the key principles of AI content optimization. |
Direct opening with specific claim: AI-citable
Enterprise brands that restructure existing content for AI extractability without adding net-new pages achieve between 37x and 761% growth in LLM platform traffic within a single engagement. The changes are structural, not volumetric: question-format headings, direct opening answers, and EAV-precise body copy. |
The second version is citable because it contains an entity (enterprise brands), an attribute (restructuring existing content), and a value (37x to 761% growth). The first contains no citable facts. Both could open the same article.
How Should You Structure H2 Headings for AI Citation?
The heading structure of a piece of content is the primary signal AI retrieval systems use to understand what each section covers. A statement heading labels a topic. A question heading signals that the following content answers a specific question. The difference in AI citability is significant.
When an AI system is constructing a response, it looks for content that answers the user’s specific question cleanly and completely. A page with question H2s, each matching a likely user prompt and followed by a direct answer in the first two to three sentences, is structured so that retrieval systems can extract exactly what they need. A page with statement H2s requires the system to infer what question the section is answering, which introduces uncertainty and reduces citation likelihood.
| Statement H2: harder to cite
The Importance of Schema Markup for Modern SEO |
Question H2: citation-ready
What is schema markup and how does it improve AI search visibility? |
The question headline (H2) is easier to read by humans than the standard headline (H1). It’s easier to scan because it clearly conveys what the area of the page will contain. Question headlines are the one thing you can do to see the greatest immediate impact on your use of Artificial Intelligence (AI) to cite your content. All you have to do to convert a statement headline into a question headline is make a single change – add a question mark at the end of your headline. This will not require you to create any new content, conduct any new research or increase the total number of words you’ve written.
Once you’ve made your H2 a question headline, the Extractable Unit Principle will determine how the first few sentences need to perform. The Extractable Unit is the first Heading you see, followed by 2-3 sentences immediately underneath the heading. In combination, these should provide a full, independent Answer to the original query. Any remaining content within the page will provide Supporting Detail, Evidence and Context for Human Readers.
Mochi Shoes reached 761.43 percent growth in LLM-platform traffic as a result of Content Restructuring (applying the Extractable Unit Principle) to all Product Pages and Category Pages without adding net-new content. Mochi Shoe had previously created their content but did not structure each section to lead with a direct answer. Case Study published here: infidigit.com/mochi-shoe-llm-strategy-case-study/
HDFC Life Term Insurance achieved 90+ AI Keyword Placements and 76.19X growth in LLM Traffic using Content Work that treated the structural elements of Term Insurance Priority Page(s) using EXACTLY this same structural methodology. Published case study: infidigit.com/case-study/
What Is EAV Structure and How Do You Apply It to Every Claim?
Entity-Attribute-Value structure is the principle that every substantive claim in a piece of content should name an entity, state an attribute of that entity, and give a specific, verifiable value for that attribute. EAV-structured claims are citable. Generic claims are not.
The test for whether a sentence is EAV-structured is simple: can you draw three labeled boxes around it and write the entity name, attribute, and value? If yes, it is citable. If the sentence is too vague to fill one of those boxes, it is not.
| No EAV structure: not citable
Our enterprise SEO services have helped many leading brands significantly grow their organic traffic and improve their digital presence. |
EAV-structured: Entity (D&B) / Attribute (LLM sessions, AI Overview placements) / Value (57x, 1,500+, 3 months)
Infidigit’s LLM SEO engagement for Dun & Bradstreet, a global B2B data and analytics platform, produced 1,500-plus keyword placements inside Google’s AI Overviews and a 57x increase in sessions from LLM platforms within three months. |
The EAV requirements have changed what writers need prior to starting writing. In order for the writer to be able to produce an EAV-compliant piece, the brief must include the exact claims the piece should be making (with supporting evidence), attributed to whom.
If the brief states “how do enterprise brands improve AI visibility?” but does not state verifiable claims, then no matter how good the structure of the content is – the resulting content will be vague and non-citable.
Add a “Claims to Support” section to your brief, stating the top three to five verifiable claims the article is supposed to make — each including a source/data-point. Writers are expected to write EAV-precisely stated, as opposed to doing all original claim research.
The content restructuring work we did at ICICI Prudential Life Insurance required the same level of discipline: taking existing product/category content and structuring all major claims to reference a specific entity, attribute & value. This resulted in our having 1,093 AI Overviews placed on keyword search results (and) a 39X increase in LLM platform session engagement. Published case study: https://www.infidigit.us/case-studies/icici-llm-strategy/
Why Are FAQ Sections the Most Under-Utilized Citability Asset in Enterprise Content?
Most enterprise content has FAQ sections. Almost none of them are structured correctly for AI citation, and almost none have FAQ schema markup applied. These two failures together mean that the most naturally extractable content on most enterprise pages is invisible to AI systems in structured form.

The FAQ section problems are consistent across everything we audit:
- FAQ answers are too long. A 250-word answer to a question that could be answered in 45 words is not an extractable unit. AI systems looking for a clean answer will skip it in favor of a shorter, more direct answer on a competing page.
- FAQ questions are not written as the buyer would actually phrase them in an AI assistant. Questions written as ‘What is the importance of X’ will not match prompts phrased as ‘Why does X matter for enterprise brands?’
- FAQ answers are not structured as complete standalone responses. They assume the reader has read the rest of the article. An AI system extracting only the Q-and-A, without surrounding context, should still receive a complete, accurate, useful answer.
- FAQ schema markup is absent. Without FAQ schema, question-and-answer pairs exist only in unstructured HTML. They are readable by AI crawlers but not machine-readable as structured data objects.
The B2B ecommerce platform that achieved 245x improvement in AI Overview keyword presence had structured data implementation as a primary solution element. The case study specifically calls out missing structured data as one of the core starting challenges, and FAQ schema implementation as part of the fix. Published case study: infidigit.us/case-studies/b2b-ecommerce-seo/
| The correct FAQ answer format
Question: How long does it take to see results from LLM SEO? Correct format: Brands that implement the full LLM SEO framework, covering technical crawlability, content restructuring, schema implementation, and off-site entity clarity, typically see measurable increases in AI citation frequency within 60 to 90 days. Significant traffic growth from LLM platforms generally becomes visible within three to six months. Infidigit’s engagement with Dun & Bradstreet produced a 57x increase in LLM sessions within three months of structured implementation. This answer is 51 words, directly responsive to the question, and includes a specific verifiable claim. It is complete without surrounding context. That is the standard. |
What Schema Markup Does an AIO-Targeted Article Actually Need?
Structured content with a clear, organized format (EAV) in an Internet web page will be transformed into “machine readable” items via schema markup. An internet web page containing high-quality EAV-formatted content without any schema markup forces AI’s to extract structural elements of the data from the unstructured HTML. The exact same content on a different internet web page, but now formatted as per the schema markup guidelines, allows for explicit, machine-readable signals for those retrieval systems to utilize when attempting to retrieve or classify the information contained within it with increased confidence and accuracy.
The minimum viable schema set for a piece of AIO-targeted content:
- Article or BlogPosting schema on every authored content page. This marks the content as a discrete, citable piece with a named author, publication date, modified date, and headline. Without it, the page is treated the same as any other HTML document.
- Person schema for the author, linked to the Article schema via the author property. For content published under Kaushal Thakkar’s byline, Person schema should include his name, job title, employer (linking to Organization schema for Infidigit), and a sameAs reference to his LinkedIn profile URL.
- FAQ schema on every page that includes a Q-and-A section. Each question and answer pair is individually marked up in JSON-LD so AI retrieval systems can extract them as independent structured data objects, not just as HTML text blocks.
- HowTo schema on any page that describes a step-by-step process. The global ecommerce platform engagement that produced a 1,139x increase in AI-generated traffic included enhanced schema markup as a core technical solution, covering Product, FAQPage, and BreadcrumbList schema types. Published case study: infidigit.us/case-studies/global-ecommerce-platform-llm-strategy/
- Organization schema on the domain homepage, linked from Article and Person schema via the publisher and author properties. This is the entity anchor that allows AI systems to verify that the content comes from a known, verifiable organization.
The creation of schema is not something that writers can do. This task falls to developers or CMS administrators. However, determining which schema types will be used by including them in the content brief helps ensure that all required schema types are included as determined within the content brief. A brief specifying “This article contains a 5 question FAQ section” indicates the need for an FAQ schema type. In addition, including schema requirements in the brief ensures that they will always be included from the time of writing until publication.
How Do You Write for Conversational AI Prompts Without Abandoning Keyword SEO?
Traditional Keyword Optimization focuses on short, noun-rich queries from potential customers that they enter into Google: ‘Enterprise SEO Agency‘, ‘LLM SEO Services‘, ‘Overview of AI Search Engine Optimization’. Although those types of searches can still be used as references for traditional search, it would be good to include those same queries in your Title Tags, H1s, and Meta Descriptions.
However, the way users enter their questions into chatbots (ChatGPT or Perplexity) differs from the structural form of how users enter their questions when searching using traditional methods. Users entering their requests into chatbots do so by writing complete sentences and using natural language: “What is the best Enterprise Brand LLM SEO Agency to hire in the United States?”, “What is the Difference Between AIO, GEO and LLM SEO?”, “How Long Does It Take to Increase Your Large Brand’s Visibility Using AI Search?”
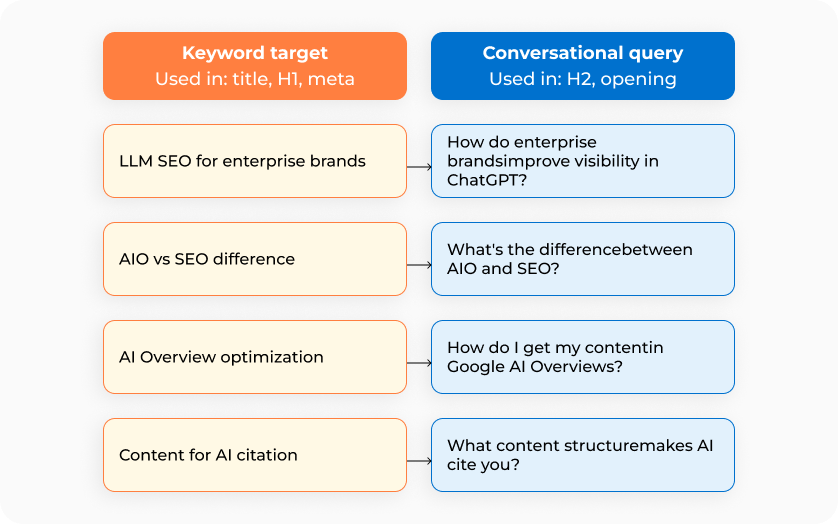
Since you may have developed some content that uses brief, keyword rich phrases, that content will likely not provide the same response as content that includes natural language question headings to respond to conversational chatbot prompts. Therefore, each section of this project should include two items: one item representing the target keyword for traditional search and another item representing a corresponding conversational prompt to achieve citability through artificial intelligence.
| Traditional keyword target | AI conversational query equivalent |
| LLM SEO for enterprise brands | How do enterprise brands improve their visibility in ChatGPT and Perplexity? |
| AIO vs SEO difference | What is the difference between AIO and traditional SEO for enterprise brands? |
| AI Overview optimization | How do I get my brand’s content to appear in Google’s AI Overviews? |
| Content for AI citation | What type of content structure makes it more likely that an AI system will cite my brand? |
| AIO measurement metrics | How do I measure whether my AIO program is actually working? |
When the writer sees both columns, they understand that the H2 heading should be written closer to the conversational query format, while the page title and H1 reflect the keyword. Both purposes are served by one piece of content written from one brief.
How Should Internal Links Be Specified in a Content Brief?
Internal links are also dual purpose. On one hand, they indicate the topicality of the linked-to-content as well as the hierarchical structure of the site. In terms of PageRank flow from a traditional search engine optimization (SEO) point-of-view, internal links will pass PageRank. In terms of AIO, however, internal links provide signals to artificial intelligence-based retrieval systems as to how your content is interconnected as well as what type of semantic relationship exists between the pages.
From a generic vs. descriptive anchor text point-of-view, there is no other difference between the types of anchors; the difference lies solely in the words used in the anchor. Generic anchor text such as “Learn More”, “Read Here”, “Click Here” tells you absolutely nothing regarding the subject matter or topic of the page being referenced. The opposite is true of descriptive anchor text; for example, “How Enterprise Brands Implement LLM SEO at Scale”, this tells you the subject matter of the destination page as well as the relationship between the source and destination pages.
As part of each content brief writers should be informed which internal links need to appear within the writing assignment and, more importantly, exactly what anchor text needs to appear on those links. For example, instead of asking writers to “Link to our LLM SEO Service Page”, ask them to “Link to our LLM SEO Service Page using Anchor Text: Infidigit’s LLM SEO Services for Enterprise Brands”. Writers choosing their own link wording can result in random navigational anchor text appearing across a full content estate. Consistent and semantically meaningful anchor text can only occur when writers receive clear direction regarding specific link wording requirements.
Why Does Citing External Sources Make Your Own Content More Citable?
Counter-intuitively, an extensively observed AIO Content Work Principle: Content citing verifiable, outside sources are cited more frequently by AI Systems than Content claiming the exact same thing without such source citations.
Corroborating evidence exists for the mechanism. AI systems consider content to be more valuable if their claims correlate with and are corroborated by additional, previously trusted, sources. A piece of content that includes citations to studies from McKinsey, reports from Semrush or datasets from the U.S. Government signals how related the content is to trusted external references. The Signal provided by inclusion of citation is functionally equivalent to a SameAs reference in the Organization schema; i.e., connecting your content to a web of trusted references rather than treating it as an isolated/unverifiable claim.
The Semrush AI Visibility Index 2026 identified this as one of four key factors distinguishing Brands who achieve persistent AI Visibility: ownership of content that AI cannot recreate based upon other sources combined with Citation Infrastructure that links that content to multiple, previously trusted External References.
The Pre-Publication AI Citability Checklist
Use this checklist before any AIO-targeted piece is published. It should take three minutes. If any item cannot be checked, the piece goes back to the writer or developer before it goes live.
| □ | The first sentence of the article body makes a specific, verifiable claim relevant to the article topic |
| □ | The first 200 words contain at least one EAV-structured statement: entity named, attribute stated, value specific and verifiable |
| □ | Every H2 heading is written as a question, not a statement |
| □ | The first two to three sentences under every H2 give a standalone, complete answer to the heading question |
| □ | FAQ answers are 40 to 80 words each. Each answer is complete without surrounding article context |
| □ | FAQ questions are written in natural language conversational format, not keyword format |
| □ | Article or BlogPosting schema is implemented in JSON-LD with author, datePublished, dateModified, and headline completed |
| □ | Person schema is implemented for the author with name, jobTitle, employer, and sameAs linking to the author’s LinkedIn URL |
| □ | FAQ schema is implemented in JSON-LD for every Q-and-A section on the page |
| □ | HowTo schema is implemented if the page contains a step-by-step process |
| □ | Every internal link uses descriptive anchor text specified in the brief, not generic text such as learn more or read here |
| □ | At least one external primary source is cited with a specific data point attributed to the original publication |
| □ | US English spelling used throughout: specialize, optimize, recognize, not specialise, optimise, recognise |
| □ | No AI-generated text has been layered onto existing content. The piece is a coherent first draft, not a composite |
| □ | Author byline is present with full name, title, and company |
What to Add to Your Content Brief Starting This Week
The changes described in this article do not require a new content management system, a new agency, or a new content team. They require a different brief.
Here is what to add to your current brief template starting this week:
- Target keyword: the primary keyword this piece supports in traditional search
- Target prompt: the natural language question this piece should answer in AI assistant responses. One prompt per section.
- First 200 words requirement: the piece must open with a direct, specific answer containing at least one EAV-structured claim. No preamble, no context-setting paragraphs.
- H2 structure: list each H2 as a question. The writer does not choose their own H2 format.
- Extractable unit requirement: each H2 section must have a 40-to-60-word standalone answer in the opening sentences before any supporting detail.
- FAQ specification: list the five to eight questions the FAQ section should address in conversational format, with a maximum answer length of 60 words per answer.
- Claims to support: three to five specific, verifiable claims the piece should make, each with an attributed source. These are not optional.
- Internal links: list each destination URL and the exact anchor text to use. Do not allow writers to choose their own anchor text.
- Schema required: specify which schema types the developer needs to implement. Article, Person, FAQ, HowTo as applicable.
- Outbound citations: name one or two external sources to cite with specific data points.
All of the additional requirements need no more than a sentence or two to add to your brief. When you follow this process, your content team will create an AIO (authoritative, informative, and optimized) brief with the potential for citation-ready content. The cumulative benefit of doing so for all pieces created by your team over the course of the next 12 months, is a content estate with most pages being capable of being cited using AI. This accumulation of effort creates the kinds of numbers we have seen at Flipkart Seller Hub, which experienced 37X year-over-year growth in LLM session engagements due to making AI citability the first priority when creating every brief. Not just an option you can use after publishing.
Published case study: infidigit.com/flipkart-seller-hub-llm-strategy-case-study/

Kaushal Thakkar
Founder & CEO, Infidigit