
Although the original Topical Authority (TA) systems were created using the idea that Search Ranking is determined by semantic Content Network Coverage and Entity-Level Coverage, the TA Systems have shown to be durable and successful. Koray Tugberk Gubur’s topical authority and semantic SEO research developed the basic terminology related to this method: topical maps, source context, entity attribute value structure, and the semantic content network as the system of operation for establishing search authority. All these concepts continue to apply today.
They do not provide information about the process of how large language models find, trust and reference content. The surfaces through which buyers currently see Brands – such as ChatGPT, Perplexity, Gemini, Google’s AI Overviews and AI Mode – evaluate content based on different and partially separate sets of criteria compared to the signals used by Google’s traditional ranking algorithms. Brand can be number one for their primary keyword and completely absent in the AI Overview sitting atop the number one listing.
It isn’t a hypothetical example. An Ahrefs study analyzing 1.9 million AI Overview citations found that 76% of those cited pages also appeared in Google’s top 10 organic rankings. Meaning ranking position and citation were almost synonymous. By February 2026, an additional Ahrefs study isolated just standard organic listings and found the overlap had decreased to 37.1%, while BrightEdge’s simultaneous tracking showed a similar directional trend. Within less than a year, having the top organic rank was no longer a reliable indicator of being cited within an AI; it was simply one piece of data a model would weigh alongside other off-page metrics.
The Infidigit AI Discovery Framework is a Practitioner’s Methodology that extends established principles for Topical Authority related to traditional search into the specific mechanics of AI-based discovery. The five layers include: Foundation, Semantic Architecture, AI Extractability, Entity & Citation Authority, and Measurement. Each Layer will contain specific actionable elements developed directly from Infidigit’s delivery history of Enterprise and Mid-Market Brands. Included throughout are selected Case Studies with Verified Results.
The Infidigit AI Discovery Framework is intended to be utilized by Practitioners. It should be referenced, tested, and modified by others who operate in this field.
Introduction: Why a New Framework Was Necessary
I’d like to begin by making a counterintuitive claim: Brands that lose visibility from answers created using AI are rarely losing visibility because their content isn’t good. In most instances, they’re losing visibility because their content was optimized for an older, different search engine retrieval system.
Google’s traditional ranking algorithm assesses each site based on many variables (hundreds) that have been collected over time or even months/years. Those results are returned in a ranked list and a person will read that list before deciding how to proceed. Over twenty years the rules that govern this process have become very familiar. Authority signals, topical coverage, and both technical and content quality. Koray Tugberk Gubur’s semantic SEO framework is probably one of the best and most scientifically supported ways to optimize for Google’s ranking algorithm. Therefore, it is also the basis upon which we build our traditional SEO strategy at Infidigit.
AI-generated responses function quite differently than Google’s ranking algorithm. If someone asks ChatGPT a question, the platform will find possible sources related to the user’s question; generate a new written answer to the user’s question in ChatGPT’s own voice; and determine which source(s) to reference when generating the answer. The method used to select references is a citation determination, rather than a ranking of candidates. While there is some overlap between what determines citations and what determines rankings, these processes do differ.
Three specific gaps motivated the development of this framework.
First: the keyword-prompt structural gap. In traditional SEO, the optimization target is a keyword. In AIO, the optimization target is a prompt, a natural language question that a buyer types into an AI assistant. These are different linguistic structures with different implications for how content must be organized. Critically, however, the same piece of content must serve both. You cannot write one version of a page for keywords and another for prompts, because they share the same URL, the same heading structure, the same paragraphs. Separating keyword optimization from prompt optimization, either into different content briefs or different teams, produces contradictory requirements that undermine both outcomes simultaneously.
Second: the off-site entity gap. Traditional SEO’s external signal is the backlink, a reference from another page to yours. LLMs do not evaluate backlinks. They evaluate whether a brand is described consistently and authoritatively across the third-party sources the model was trained on or retrieves during inference: G2, Clutch, Wikipedia, press coverage, analyst reports, community discussion. A brand whose own website is excellent but whose third-party description is inconsistent, outdated, or absent will be cited poorly or not at all.
Third: the technical infrastructure gap. Most AI-focused content guidance addresses what to write. Almost none addresses whether AI crawlers can actually access and read it. A growing number of enterprise sites unintentionally block GPTBot, ClaudeBot, PerplexityBot, and related crawlers at the CDN or robots.txt level, making every other optimization effort irrelevant. This is the infrastructure layer that sits underneath all content work, and it is frequently ignored.
The Infidigit AI Discovery Framework was built to address all three gaps, within a structure that connects directly to the traditional topical authority foundation rather than replacing it.
Framework Overview: The Five Layers
The framework is organized into five layers that should be implemented in sequence. Each layer is a prerequisite for the one above it. Investing in Layer 3 before completing Layer 1 is the most common reason AIO programs produce inconsistent or non-durable results.
| Layer 1 Foundation Technical infrastructure for AI discovery
Crawlability AI crawler access, robots.txt, CDN configuration, JavaScript rendering Indexability Canonical signals, sitemap health, structured data baseline llms.txt Plain-language site description for LLM ingestion Core Web Vitals Page experience signals that support both ranking and content credibility |
| Layer 2 Semantic Architecture Topical authority for both search and AI
Topical map Hub-and-spoke content hierarchy covering the full topic space without gaps Semantic content network Contextual internal linking that builds topical relationships between pages EAV content structure Entity-Attribute-Value precision in every piece of content Author entity Named expert attribution with Person schema on all authored content |
| Layer 3 AI Extractability Making content citation-ready for LLMs
Extractable unit structure Every H2 section independently citable as a standalone answer Prompt-keyword integration Single content brief serving both keyword and conversational prompt targets Direct answer architecture 40-to-60 word answer in the first sentences under each heading Schema for AI systems Organization, Article, FAQ, HowTo, and Dataset schema as applicable |
| Layer 4 Entity & Citation Authority Off-site signals that LLMs trust
Entity consistency audit Consistent brand description across G2, Clutch, Wikipedia, press, LinkedIn Third-party citation pipeline PR, review generation, analyst briefings as a quarterly operational function Co-citation signals Deliberate earning of mentions alongside trusted brands in the same context Training data presence Historical content depth that creates cumulative weight in model knowledge |
| Layer 5 Measurement Connecting AI visibility to business outcomes
Citation rate & share of model Prompt-based audit tracking across ChatGPT, Perplexity, Gemini, AI Overviews GA4 AI Assistant channel Native and supplemented AI-referred session tracking Search Console Generative AI Impression-level data from Google’s AI features (launched June 3, 2026) Branded search lift Downstream signal of AI awareness converting to direct recall |
Layer 1: Foundation
1.1 AI Crawler Accessibility
The first question any AIO program must answer is not about content. It is about access. Can the AI systems you want to be cited by actually read your website?
GPTBot (OpenAI), ClaudeBot (Anthropic), PerplexityBot, and GoogleOther (used for AI Overview training and retrieval) are the primary AI crawlers to accommodate. Each needs to be checked against three potential access barriers.
robots.txt
The most common issue: robots.txt files that block all bots using a wildcard disallow directive, or that were written before AI crawlers existed and have never been updated. Check your robots.txt for any Disallow: / directive that applies to User-agent: * without explicitly allowing the AI crawlers by name. If your robots.txt contains User-agent: * followed by Disallow: /, add explicit Allow directives for each AI crawler above the wildcard rule.
CDN and Infrastructure Blocking
Cloudflare, Fastly, and similar CDN providers offer bot management features that can block AI crawlers without any explicit configuration by the site owner. Challenge pages, JavaScript challenges, and bot score thresholds can all prevent AI crawlers from reaching your content even when robots.txt permits access. Check your CDN’s bot management settings specifically for the AI crawler user agents listed above. This is particularly common on sites that implemented aggressive bot blocking after experiencing AI scraping concerns.
JavaScript Rendering
Most AI crawlers do not execute JavaScript. Content that requires JavaScript to render, including page content loaded via fetch or XHR after initial page load, SPAs where the main content is injected by a framework, and product data loaded dynamically, will be invisible to non-rendering crawlers. For pages you want to be cited, the substantive content must be present in the raw HTML response, not injected by JavaScript after load.
A practical test: disable JavaScript in a browser profile and load your priority pages. The content that renders is what AI crawlers can access.
1.2 llms.txt
llms.txt is an emerging convention for providing AI systems with a plain-language description of a site’s content, purpose, and key pages. It sits at the root of the domain, analogous to robots.txt, and is being incorporated into AI crawlers’ site assessment logic.
A well-written llms.txt file describes what the site does, who it serves, what its most important pages are, and what claims the site can authoritatively support. It is not marketing copy. It is a structured description of the site as a source of information. Both infidigit.com and infidigit.us maintain llms.txt files; the content should be reviewed at least quarterly to ensure it accurately reflects current services and positioning.
1.3 Structured Data Baseline
The minimum viable schema for AI discoverability is Organization schema at the domain level, covering name, URL, logo, description, founding date, and sameAs references to verified external profiles: LinkedIn, G2, Clutch, and any other platforms where the brand has an authoritative presence. This schema does two things: it gives AI systems a machine-readable, authoritative description of the brand, and it establishes the entity identity that off-site citations can corroborate. Without it, AI systems attempting to describe your brand must infer facts from unstructured text, which produces inconsistency.
Layer 2: Semantic Architecture
This layer draws most directly from the established principles of topical authority. Koray Tugberk Gubur’s framework established that search authority is earned through comprehensive coverage of a topic space, not through individual high-performing pages. The same principle applies in AI-driven discovery, with an important extension: LLMs evaluate topical authority through the same signals, but they additionally weight the density and precision of individual content units within that structure.
2.1 The Topical Map
A topical map is a hierarchical structure of all the subjects and subtopics that will be covered on a website about a particular subject area. It is not a calendar for creating content or a list of keywords. The topical map is a map of the entire subject area (the knowledge space) that a website claims as its area of expertise. This is done by starting at the most general or broadest subject, then breaking it down into subtopics and finally into even smaller areas of focus called microtopics.
Once a topical map is created, the next step is to develop the map further by establishing the main entity/subject matter for which your company has some type of legitimate credibility. In our case, this was organic growth using artificial intelligence to help enterprise companies discover new customers and markets. All topics and subtopics included in the topical map need to have logical connections back to the main entity. If there is no clear connection, they represent either gaps in the topical map or areas where your business does not have real-world authority.
Ultimately, a well designed topical map will tell you exactly what types of content you should produce; when you should produce them; how they should be linked together; and what areas of authority you may be missing. Missing areas of authority can lead to your website being viewed as less than authoritative by search engines as well as by Large Language Models (LLMs).
A location page and/or service pages are NOT a topical map. These pages serve as sales pages and sit above the topical map. An Agency’s topical authority architecture is comprised of the informational and educational content that supports their commercial pages and helps establish authentic authority in their field for both crawling algorithms and LLM retrieval systems.
2.2 Semantic Content Network
The semantic content network is a collection of the internal hyperlinks that connect the various web pages throughout your topical map. One of the most often misinterpreted aspects of website structure is the difference between navigation hyperlinking (i.e., menu items, footers, breadcrumb links) and semantic hyperlinking (i.e., anchor text within body content).
Navigation links inform crawlers on how to navigate through your site. Semantic links provide both a crawler and an LLM retrieval model with information regarding the relationship between two individual pieces of content. For example, when a link from a page relating to Enterprise AIO directs users to a page relating to Off-Site Entity Clarity, and includes the anchor text “How Third-Party Citation Consistency Influences the Frequency of Citations by Artificial Intelligence”, you are communicating a specific topic-based relationship. When the same link uses the anchor text Learn More, you are communicating nothing.
Every internal link used as part of the body content should include sufficient description of the subject matter being described at the destination URL so that it is apparent from the anchor text itself the type of relationship that exists between the two pages. It is simultaneously beneficial for traditional ranking methodologies and is important for AI-based retrievability because LLMs rely upon contextual signals in order to develop their own conceptualization of how a given site’s content relates.
2.3 Entity-Attribute-Value Structure
EAV structure is the principle that every substantive claim in a piece of content should identify an entity (the subject), an attribute (a property of that entity), and a value (a specific, verifiable fact about that attribute). It is the difference between a sentence that sounds authoritative and a sentence that is authoritative.
| Generic (low AI citation value):
“Infidigit delivers exceptional results for enterprise clients through our proven methodology.” EAV-structured (high AI citation value): “Infidigit’s LLM SEO engagement for Dun & Bradstreet, a global B2B data and analytics platform, produced 1,500-plus keyword placements inside Google’s AI Overviews and a 57x increase in sessions from LLM platforms within three months, starting from a baseline where content was SEO-optimized but not structured for AI extraction.” |
The second sentence is citable. It identifies an entity (Dun & Bradstreet), attributes (LLM sessions, AI Overview placements), and values (57x increase, 1,500-plus placements, three months). An LLM can extract and cite it precisely. The first sentence cannot be extracted in any meaningful way.
2.4 Author Entity
A brand’s human expertise is made into an actionable signal for machines using the mechanism of an “Author Entity”. Both Search Algorithms and LLMs assign greater value to Content that is written by a verifiable human expert whose qualifications have been vetted from multiple outside sources.
As such, every Substantive Article published by Infidigit will include a Byline identifying the article writer as Kaushal Thakkar along with his title. Every article will also contain a Consistent Short Bio that ties Kaushal Thakkar’s expertise directly to AI-Driven Discovery and includes the Person Schema linking back to his LinkedIn Profile as well as any other references to him online. Across all publishing platforms, the exact Photo of Kaushal Thakkar is displayed, so there is no question regarding the Visual Identity reinforcing the identification of the Author Entity.
Ultimately, we want each time a Search Engine or LLM evaluates Content on either infidigit.com or infidigit.us, they are able to confirm the identity of the author and determine if the author’s expertise has credibility through outside sources. This should lead them to further believe in the trustworthiness of the content. This is the way Experience, Expertise, Authoritativeness, and Trustworthiness (E-E-A-T) work for each individual article and apply to how LLMs weigh Sources in their citation evaluations.
Layer 3: AI Extractability
This is the layer with the least practitioner consensus and the most room for original contribution. The principles here are drawn from Infidigit’s direct experience with what content structures produce consistent AI citation, cross-referenced against the published research on how LLM retrieval systems evaluate and select sources.
3.1 The Extractable Unit Principle
When an LLM pulls a source of information to help build an answer, it doesn’t pull the whole article like a person reading would. Instead, the LLM pulls what’s called a “unit” of content which usually includes one or several paragraphs that best and most completely answer its question.
If this unit has enough background information to make sense by itself, the LLM may choose not to pull the unit, or it could pull too little information.
Practical Implication – Every section of every page should be written in a manner where the first two-three sentences are able to stand alone as independent citations. Each heading on the page should be in the form of a question. Each heading should include a complete sentence (or sentences) answering the question posed. The remainder of the section should provide additional support and/or evidence as well as background information to enhance understanding.
This format is useful from multiple perspectives; it meets both Google’s NLP parsing requirements for featured snippets, it meets LLM retrieval needs, and it creates better-written articles for humans.
This is different from creating FAQs out of each and every article on your website. The extractable unit concept applies to all types of content such as long-form analysis, case study, and pillar articles. An example of a pillar article may contain ten separate units of extractible content – each with their own unique question-based heading along with the corresponding direct answer.
3.2 The Keyword-Prompt Integration Thesis
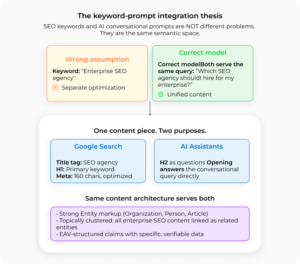
While this is perhaps the Framework’s greatest contribution to its understanding of how digital marketing works today — and while I think it may be the most commonly misinterpreted by practitioners in their own work today — the core idea is very simple.
The underlying premise for nearly all AI SEO efforts today is that keyword optimization (and prompt optimization) are separate projects that should either be completed by different individuals or at different points in time relative to the creation of the content. In fact, this premise is wrong — when done incorrectly, the resulting content will not perform well on either surface.
Why? Because there is exactly one keyword that activates a traditional search engine to return a ranking for the content, and there is exactly one prompt that will activate an LLM to cite your content. That same piece of content has to have enough substance and breadth to rank for a keyword cluster; that same piece of content must also be broken down into extractable units that allow LLM citation; those same headings that allow a search engine to identify a featured snippet are the same headings that allow an LLM retrieval system to understand what part of the content is being referred to; and finally, those internal links that transfer topical PageRank from one piece of content to another are also those internal links that indicate semantic relevance to LLM retrieval systems.
It simply doesn’t matter how much content you create; there isn’t going to be a situation in which you can write paragraphs to optimize for keywords, and then go back and write entirely new paragraphs that are optimized for a prompt. What matters is whether the content was created with both goals in mind as one simultaneous project; if they were, the paragraph(s) will meet both requirements. If they were not, then those paragraph(s) do not meet either requirement.
To determine if you are working within an integrated or split model today, take the latest content brief issued for any page on your website and see if that brief includes both keyword-based requirements AND conversational prompt-based requirements in the same document. If it does NOT include both types of requirements in a single document, then you are operating in a split-model regardless of who claims ownership of both models on paper.
3.3 What AI Content Layering Tools Actually Do
Beginning with the emerging class of tools designed to generate additional AI-written content (and place it atop) other than what already exists, there’s an idea being sold that you can take your pre-existing (human written) content; use that for traditional Search Engine Optimization and then add on AI specific content to make that same content “visible” in AI generated answers. This doesn’t work. And when applied to any content, it harms that content. The reasoning is based upon linguistics (coherence). Large Language Models (LLMs) were created to recognize authorship (who wrote the content), and authority (the level of expertise of the writer). Therefore, when AI generated sentences are added to a piece of human written content, the resulting product will be two completely different writing patterns contained within one single document: the original content which contains its own unique voice, depth, and authority signals; and the newly inserted layer containing only generic, pattern matched attributes. The authority of the original content is diminished. The overall quality of the page diminishes across multiple dimensions.
Similarly, the results regarding the citations and ranking follow the same pattern. As the original quality signals that support those rankings are compromised through the addition of the inserted noise, traditional search engine rankings begin to erode. Similarly, AI citation frequencies either drop significantly or remain low as the clarity and extractability of the content that supports citations are similarly damaged due to the insertion of noise.
Prior to using Infidigit services, we have seen this exact phenomenon occur with many brands who utilized these types of tools to create their content. Without fail: first, was a period of initial stability; secondly, was a measured decline in both organic rankings for traditional search engines, and thirdly, was a measured decline in AI citation frequencies as the brand’s content estate continued to fill with hybrid pages that supported no retrieval system well. In all cases, the remedy involved removing the AI-generated layers and restoring the original structure of the content, rather than creating more layers.
The proper utilization of AI tools within a content workflow is as a resource for providing insights and information regarding research. It should never be relied upon as a means for generating new content that would then be layered upon existing pages. A platform such as Semrush provides various tools including keyword data, competitor citation analysis, and AI visibility tracking. The data obtained from utilizing these tools can inform a brief. The brief is then completed via an agency or internal team responsible for executing the writing of new content per that brief. There is a clear distinction between how tools provide intelligence and how humans create content.
3.4 Schema Markup for AI Extractability
Schema markup was originally designed to help Google’s crawlers parse structured information for rich results. In the AI era, it performs an additional function: it provides machine-readable, structured versions of claims that LLMs can retrieve with higher confidence than they can extract from unstructured prose.
The minimum viable schema set for AI extractability includes:
- Organization schema at the domain level, with name, URL, logo, description, foundingDate, numberOfEmployees, and sameAs references to all authoritative external profiles.
- Article schema on all authored content pages, with author (linking to Person schema), datePublished, dateModified, and headline.
- Person schema for the author entity, with name, jobTitle, worksFor (linking to Organization schema), and sameAs referencing LinkedIn and any external citation sources.
- FAQ schema on pages that include a question-and-answer structure, with each Q and A pair individually marked up.
- HowTo schema on pages that describe a process or methodology with discrete steps.
The sameAs connections between Organization schema, Person schema, and external profiles are particularly important. They create a verifiable entity graph that LLMs can traverse to corroborate facts about the brand and its representatives, rather than relying on any single page as the only source of that information.
Layer 4: Entity & Citation Authority
Layer 4 is where the framework most significantly departs from traditional SEO’s external authority model. In traditional SEO, external authority is measured primarily through backlinks: references from other pages to yours, weighted by the authority of the linking page. LLMs do not evaluate backlinks. They evaluate entity consistency and citation corroboration across a completely different set of sources.
4.1 The Off-Site Entity Audit
Brands are often represented in multiple ways when a large language model (LLM) is trained or infers information about them. Generally, this is comprised of both the total number of sources contained in their training data, as well as all sources they may retrieve while being used. Typically, the most impactful representations do not include the company’s own website. Rather, they tend to include G2 and Clutch listings; Wikipedia entries; press articles in credible media outlets; analyst reports; LinkedIn Company Pages; comments on Reddit; and videos on YouTube.
The amount of representation each type of source receives can be quantified and varies greatly. An examination by Semrush of 150,000 LLM citations for the models ChatGPT, Perplexity, Gemini, and AI Overviews found Reddit was the referenced source 40.1% of the time; Wikipedia was referenced 26.3%; YouTube was referenced 23.5%, and that no single other domain exceeded 5%. The ranking among cited types of sources varies and is unstable. According to Semrush’s own study examining ChatGPT specifically, the frequency at which Reddit was referenced decreased from approximately 60% to less than 10% in just under five weeks from late August through early September 2025 after an open change by OpenAI. The share then partially recovered. The fact that the rankings change so rapidly makes it impractical to create a citation plan based on even a quarter’s worth of platform weightings and therefore supports the recommendation for a quarterly review cycle instead of making a one-time bet on a particular channel.
A caveat to the generalization of a dominance of Reddit and Wikipedia references in the prior section. There were additional analyses conducted by Semrush. In addition to the prior reference to the total volume of citations examined (150,000), there was also another analysis that focused only on citations produced in response to industry-specific search terms that would better approximate the types of search terms an enterprise brand should use to monitor its online presence. This second analysis revealed that 86% of citations came from domain names related to the searcher’s specific industry (e.g., vendor content); whereas only 14% of the citations came from generic domains such as Wikipedia, Reddit or Forbes. From a practical standpoint for Layer 4 work, the creation of off-site entity presence on generic platforms will likely influence awareness of a brand for broad categorizations. On the contrary, the creation of a brand’s own topical authority (Layers 2-3) will likely have more of an impact on a user searching with intent to make a purchasing decision using industry-specific search terms.
If you describe your enterprise SEO agency as an “AI search optimization company” on your website, a “digital marketing firm” in a press release dated two years ago, and “a content marketing agency” on an analyst comparative page describing your company, an LLM has four different, partially contradictory descriptions of your company to synthesize into a final description. The end result is a generalized, diluted description that cannot be clearly attributed to any specific part of your business or is incorrectly attributed due to the model choosing the most commonly occurring wording rather than the most recent.
An entity clarity audit systematically evaluates how an entity (the brand), its main products or services, and primary claims are represented externally by checking all of the major external resources. An audit identifies discrepancies, out-of-date representations, and voids where none exist. At the completion of the audit, a ranked list of corrections and enhancements required to be made on those external platforms is provided.
This is not a one-time process. As brands evolve over time and as new information becomes available regarding brands (i.e., aged press releases, etc.) so too does the way entities are described externally. Therefore, for many enterprise brands, a quarterly entity clarity review will be sufficient as a means of maintaining consistency.
4.2 The Third-Party Citation Pipeline
An entity clarity audit corrects what exists. A citation pipeline builds what does not yet exist. The goal is to earn new mentions and structured descriptions on the external sources that LLMs trust, at a cadence that compounds over time rather than as a one-time campaign.
The practical components of a citation pipeline:
- PR and earned media: securing brand mentions in recognized industry publications, with accurate, consistent descriptions of the brand’s services and positioning. A press mention in Search Engine Land, Marketing Week, or an industry-specific publication does not just create a backlink. It creates a training data point that LLMs can retrieve as external corroboration of claims made on the brand’s own website.
- Review platform management: actively generating and maintaining G2, Clutch, and Trustpilot listings with complete, accurate, current descriptions. These platforms are frequently cited by LLMs for software and service category queries. An outdated G2 listing that describes a previous version of a product is being cited to buyers today.
- Analyst and research inclusion: briefing relevant analysts and contributing to industry reports, surveys, and comparisons. Being included in a recognized analyst comparison of AIO agencies, for example, creates a citation anchor that LLMs treat as independent validation.
- Community and forum presence: having accurate brand descriptions in communities where buyers discuss their options, including LinkedIn groups, Reddit communities relevant to the category, and Slack or Discord communities in the industry. These sources appear in LLM training data and RAG retrieval.
The commercial case for this investment holds up, if imperfectly measured. Seer Interactive’s tracking of AI Overview queries found that brands cited inside an AI Overview earn approximately 35 percent more organic clicks and 91 percent more paid clicks than non-cited brands appearing in the same result set (Seer Interactive, September 2025 study, widely re-cited through 2026). A newer Seer update reportedly finds an even larger organic gap, though we have not confirmed that figure directly against Seer’s own published page and would treat it as directional rather than final until verified. Either way, the direction holds: citation correlates with a measurable click advantage over brands appearing in the same AI answer without being named.
4.3 Training Data Presence and Historical Depth
The distinction between Layer 4 and the rest of traditional search engine optimization (SEO) lies primarily within this element of Layer 4, which also represents the area where the greatest lack of agreement exists among professionals in our field.
In order to learn about the world, Large Language Models (LLMs) are trained using the content included in their training data prior to when they reach their knowledge cut-off date. Therefore, a brand with an extended history of producing high-quality, well-referenced content will be significantly better represented in that training dataset than a brand that produced a similar volume of content in the past six months. The method by which these models determine a particular source’s influence is quite similar to how Wikipedia determines its own credibility based upon the age and depth of links present on a page; however, for LLMs, the signal is much broader than just one platform; instead, it includes all of the web.
As such, this presents an immediate opportunity for brands initiating All-in-One programs to create content that can be cited immediately, via RAG-based retrieval (which utilizes current web content), rather than waiting for the off-site entity work described in this layer to increase training data presence (which is reflective of a historical corpus). Thus, brands initiating AIO programs today would reasonably anticipate seeing improved RAG citation rates within a relatively short period of time as off-site entity work begins to take effect, whereas they would likely see improved training data presence at a slower rate, but still within a timeframe equivalent to one or two model training cycles.
Therefore, the actionable response to this phenomenon is to generate genuine citations of your company’s content over a prolonged period of time, as opposed to attempting to generate sheer volume for temporary effects on training data. Quality and consistency compound over multiple model training cycles in a manner that sheer volume cannot.
Layer 5: Measurement
Measurement in the AIO context is both simpler and more complex than in traditional SEO. Simpler because the primary metric, citation rate, is directly observable and requires no algorithmic inference. More complex because the attribution chain from AI citation to business outcome passes through multiple touchpoints that most analytics setups cannot track cleanly.
5.1 The Primary Metric: Citation Rate
Citation rate is how often your brand is mentioned by name when a defined set of prompts relevant to your category is run across ChatGPT, Perplexity, Gemini, and Google’s AI Overviews. It is the AIO equivalent of search ranking position: the direct measure of visibility on the relevant surface.
A citation rate measurement protocol requires four elements: a defined prompt set of 20 to 25 prompts that mirror how real buyers in the category phrase questions to an AI assistant; a defined set of platforms to run those prompts across; a defined cadence for running them, weekly in the first 90 days, monthly once a baseline is established; and a competitive benchmark, the same prompt set run against three closest competitors, so citation rate is understood as a share rather than an absolute number.
5.2 Native Platform Updates (2026)
Two platform updates in 2026 materially changed the AIO measurement landscape.
Google Analytics added a native AI Assistant channel to GA4’s Default Channel Group on May 13, 2026. No configuration is required. Traffic from recognized AI assistants, including ChatGPT, Gemini, and Claude, now appears as a distinct channel in standard User Acquisition reports, tagged with medium = ai-assistant. This channel captures the visible floor of AI-referred traffic, but between 35% and 70% of AI-originated sessions arrive without referrer headers (particularly from mobile apps) and remain classified as Direct traffic.
One vendor-level analysis illustrates the scale of this gap directly: Loamly’s review of 446,405 visits across its customer base found 70.6 percent of detected AI-referred sessions carried no referrer header and were being misclassified as Direct traffic in GA4 (Loamly, updated February 2026). This sits at the upper end of the range cited above and is a useful anchor figure when explaining the scale of the undercount to a client or internal stakeholder.
Google Search Console launched dedicated Generative AI performance reports on June 3, 2026, providing impression-level data for content appearing inside AI Overviews, AI Mode, and Discover’s AI features. The report covers impressions by page, country, device, and date, with data from May 18, 2026 onward. It does not include click data in its current version. Source: Google Search Central Blog, June 3, 2026.
5.3 The Attribution Challenge
AI-driven discovery creates an attribution problem that is structurally similar to the long-standing challenge of measuring brand advertising’s contribution to revenue. A buyer reads about your brand inside a ChatGPT response on a Tuesday. They search for you directly on Google on Thursday. They convert via a paid search ad on Friday. GA4 attributes the conversion to Paid Search. The AI citation on Tuesday is invisible in standard last-click reporting.
The practical response is not to abandon last-click measurement but to supplement it with upper-funnel metrics that track AI’s contribution before the last-click event. Citation rate and Search Console AI impressions measure the awareness layer. Branded search lift, the change in direct branded search volume correlated against citation rate movement, measures the recall-to-intent transition. GA4 AI Assistant channel sessions measure the conversion-stage click-through.
The stakes of closing this measurement gap are rising, not falling. Adobe Analytics’ tracking of AI-referred traffic to US retail sites found it grew 393 percent year-over-year in Q1 2026 (Adobe Analytics, April 2026 report). By May 2026, that traffic was converting 54 percent better than non-AI traffic, up from 42 percent in March, while spending 53 percent more time on site and viewing 23 percent more pages per visit than non-AI traffic (Adobe Analytics, June 2026 report). AI-referred visitors are not a marginal, low-intent audience arriving from a novelty channel. On the available evidence, they are increasingly the highest-quality traffic segment most brands have, which makes continuing to measure their contribution poorly an increasingly expensive problem rather than a rounding error.
Together, these three metrics tell a coherent story about the AI discovery funnel that no single metric tells alone.
Framework in Practice: Selected Case Studies
The following results are drawn from published Infidigit case studies. Full methodology details are available at infidigit.com/llm-case-studies/. These engagements shaped the framework described in this article; the framework is as much a documentation of what worked in real client delivery as it is a forward-looking prescription.
| 57x
Dun & Bradstreet LLM session growth in 3 months |
1,500+
Dun & Bradstreet AI Overview placements achieved |
39x
ICICI Prudential LLM session growth achieved |
Dun & Bradstreet: B2B Enterprise AIO at Scale
Beginning with the fact that Dun & Bradstreet is a business-to-business (B2B) data and analytics company operating globally, Infidigit has done an initial project of providing LLM-based visibility for this client. The beginning or “as-is” state reflected the most typical format for large enterprise brand content optimization efforts. That being said, although the brand’s content had been optimized for organic search based on traditional search engine algorithms, it lacked proper structure for extraction by artificial intelligence. In addition to these issues, there were schema inconsistencies present throughout their large-scale content estate. As a result of a very slow refresh rate on all new content published through their channels, there existed large time gaps in how quickly new content would be available in searches performed via artificial intelligence.
To begin the process outlined earlier in terms of establishing a framework of action, the first step in working with Dun & Bradstreet as a client was to complete a technical access audit. Next steps included performing entity clarity work on all platforms from which they are acquiring data for use in other applications. The final step consisted of content reorganization on those pages that are the most likely to be used as retrieval points for users who ask about related topics.
Results within three months: 57x increase in sessions from LLM platforms and 1,500-plus keyword placements inside Google’s AI Overviews. Full case study: infidigit.com/dnb-llm-strategy-case-study/
ICICI Prudential Life Insurance: Building AI Visibility in BFSI
At the start of this project, ICICI Prudential’s positioning demonstrated one common problem that many brands have with the Measurement Baseline – only about 200 words were used by the AI Assistant to trigger an overview placement; the percentage of time an overview was shown as part of an overall search (AI Assistant) was less than 3 percent.
Although ICICI Prudential had an established presence on the web through search engines, they did not structure their online content around how consumers use conversational search queries when searching via voice or keyboard through their AI assistants.
All five layers of the Framework were addressed within this project: Technical Crawlability of content from AI Bots, EAV structuring of current product and informational data, Organization and Product and FAQ and Dataset schema implementations, Entity Clarity across BFSI third-party sites, and Real Time Monitoring of new patterns for emerging AI Visibility utilizing Infigrowth (Infidigit’s AI assistant tracking platform).
Results: 1,093 AI Overview keyword placements, AI Overview share growth from 2.9% to 4.1%, and 39x LLM session growth. Full case study: infidigit.com/icici-llm-strategy-case-study/
Flipkart Seller Hub: E-Commerce AIO at Consumer Scale
Flipkart Seller Hub, as the seller-focused version of Flipkart.com, represented a unique problem: it had strong “traditional” search results for its content estate; however, there were issues with the consistency of citations for the brand name from the third-party sources that are used by LLMs to build their knowledge base on this content estate.
Layer 4 (Entity Authority and Citation Authority), along with Layer 3 Content Restructure, were targeted in the Engagement since the Entity Clarity Gap was the main cause of citation inconsistencies. Standardizing Brand Descriptions across all relevant third-party platforms; structuring content for AI-readiness, and using GA4 to track LLM sessions resulted in 37x Year-over-Year Growth in Sessions on LLM Platforms and more than 100 Keyword Placements in Google’s AI Overview.
Full case study: infidigit.com/flipkart-seller-hub-llm-strategy-case-study/
Mochi Shoes: Retail AIO Through Content Restructuring
Mochi Shoes is an example of the framework being used with a retail content challenge. The initial issues facing this project were common to the retail industry as a whole. Retail had (and continues to have) product descriptions and FAQ areas that are very “thin” in terms of useful information. FAQs also do little to answer deep user inquiries because they only address the most basic inquiries. There is typically (again, even today) limited or non-existent linking from category pages back to individual products within those categories. In addition, there was never any direct tracking of the number of users who visited through sessions referred by AI.
Mostly all of the major effort involved Layer 3: Reformatting and extracting existing content related to products and their respective categories into formats that could be extracted using AI, the implementation of Product & FAQ & WebPage & Breadcrumb schemas throughout the entire Content Estate, and changing how we optimize for the intent behind user queries (conversational query patterns), versus simply matching against specific keywords. No new content was developed during this process — the entire Content Estate was reformatted.
Results: 761.43% growth in LLM-platform sessions. Full case study: infidigit.com/mochi-shoe-llm-strategy-case-study/
| A note on case study data
All figures cited above are drawn from published case studies on infidigit.com/llm-case-studies/ and reflect verified account-level data from Infidigit’s delivery teams. The methodology sections of each case study describe the measurement approach used to produce these figures. |
What This Framework Is and Is Not
Relationship to Koray’s Framework
The Semantic Content Network, Topical Map, EAV Structure and Author Entity Components in layers 2 & 3 of the above framework were based on the principles developed by Koray Tugberk Gubur for his semantic SEO work. Koray’s framework provided the most comprehensive, publicly accessible methodology for establishing topical authority in traditional search. The Infidigit AI Discovery Framework used those principles as the basis for layers 1 & 2, acknowledged them, and extended them through the AIO-specific components in layers 3, 4 & 5 that Koray’s framework did not account for.
Original Contributions in this framework include: the Keyword-Prompt Integration Thesis; Off-Site Entity Authority Model For LLM Citation (layer 4); Practical Classification of AI Content Layering Tools and Documented Failure Modes; Five-Layer Measurement System Connecting AI Citing To Business Outcomes.
Practitioners who have acquired expertise in Koray’s Framework will find layers 1 & 2 of the above Framework Familiar. Incremental Depth is in layers 3, 4 & 5.
What This Framework Does Not Claim
This framework is a practitioner’s approach, not an academically based theory. This framework is developed on what has worked in producing measurable results in actual engagements, and its merits should be tested and validated against results as opposed to the attractiveness of a theory.
As stated earlier, the AI-driven discovery environment is evolving at a pace that is greater than the development of a completely effective framework. The behaviors of platforms as well as citation signals associated with ChatGPT, Perplexity, Gemini and other applications utilizing AI-based features from Google are correct to date (July 2026) according to our knowledge and observations. The behaviors of these and future platforms will continue to evolve. The durability of this framework’s five-layer structure, while allowing for tactical updates, is expected to endure regardless of future platform behaviors.
If anyone tells you they have a complete, permanent, and/or fully vetted method describing how LLMs make decisions regarding citations, they are misinformed or trying to sell you something. A truthful representation of this framework is: this is what we have identified that has been successful across real engagement experiences with verifiable results up until mid-2026. This is a launching point for practicing with rigor, not the final answer.
Practitioner Checklist: Framework Implementation Sequence
| Layer 1: Foundation (Complete Before Any Content Work) |
- Verify robots.txt allows GPTBot, ClaudeBot, PerplexityBot, and GoogleOther
- Check CDN bot management settings for AI crawler blocking
- Load priority pages with JavaScript disabled. Confirm substantive content renders
- Review or create llms.txt with current, accurate site description
- Implement Organization schema with sameAs references on homepage
| Layer 2: Semantic Architecture (Foundational Content Infrastructure) |
- Build or audit topical map against the full subject domain. Identify coverage gaps
- Audit internal linking for semantic (contextual) anchor text versus navigational-only links
- Review content for EAV structure: every substantive claim names an entity, attribute, and specific verifiable value
- Establish author entity: consistent byline, biography, Person schema, and headshot across all authored content
| Layer 3: AI Extractability (Content Structure for Citation) |
- Audit H2 headings on priority pages. Convert statement headings to question headings
- Add a direct, standalone 40-to-60 word answer in the first sentences under each question heading
- Create a unified content brief template that includes both keyword requirements and conversational prompt requirements
- Implement FAQ, Article, HowTo, and Person schema on applicable pages
- Identify any AI content layering tools in the workflow and evaluate their contribution to content quality degradation
| Layer 4: Entity & Citation Authority (Off-Site Work) |
- Run entity clarity audit: check G2, Clutch, Wikipedia, LinkedIn, and top five press mentions for description consistency
- Correct all outdated or inconsistent brand descriptions across external platforms
- Establish a quarterly citation pipeline: PR calendar, review generation process, analyst briefing schedule
- Monitor which external sources appear in AI responses to your top 20 prompts. Prioritize citation building on those sources
| Layer 5: Measurement (Set Up Before Optimization Work Begins) |
- Define and document your 20-to-25 prompt set for citation rate tracking
- Confirm GA4 AI Assistant channel is receiving sessions. Add Perplexity to a custom channel group
- Check Search Console for Generative AI performance report access. Export baseline page data if available
- Set up branded search volume tracking in Search Console as a downstream AI-influence proxy
- Establish a weekly citation rate tracking cadence for the first 90 days
Conclusion
The core premise of this model is that AI-powered discovery is not a new field of research, rather, it extends upon the foundational elements of search optimization (i.e., topic authority & entity clarity), with a set of additional AIO-centric attributes that traditional optimization frameworks were not designed to account for.
To succeed in AI-powered discovery over the course of the next couple of years, the winning brand will not necessarily be the one creating the most content, or utilizing the most schema type. Rather, it will be those who develop true topical authority within a well-defined space; organize their content in such a way that each subsection can stand alone in terms of being cited; provide consistent entity description across the external resources that LLMs ultimately depend on; and use a similar level of scrutiny when measuring success with AI-powered discovery as they do with traditional search.
This five-layer progression provides a roadmap to achieving this end. It is not a fast track. The work required to achieve Layer 1 is mundane but necessary. The offsite work needed to complete Layer 4 is continuous, and thus never-ending. Establishing measurement infrastructure in Layer 5 requires an upfront investment before insights become actionable. These are all long-term plays.
What they offer, though is durability. The brands that construct this foundation appropriately in 2026/27 will have a compounded advantage over time as AI-powered discovery increasingly represents the means by which consumers locate and assess solution options. Conversely, those brands that pursue “quick fix” strategies (e.g., AI-powered content layering tools, split teams, citation rate optimizations) will find that the benefits of said fixes compound in the wrong direction.
This model is intended as a starting point for discussion and collaboration, not as the final word. If you are using this model to implement your strategy, identify areas for improvement, or otherwise contribute to its development, we at Infidigit would appreciate hearing about your experiences. As the field of AI-optimized search is still relatively young, it is likely that the best future models will emerge through the collaborative efforts of experienced practitioners sharing what they learn from their individual engagements.
Kaushal Thakkar
Founder & CEO, Infidigit