
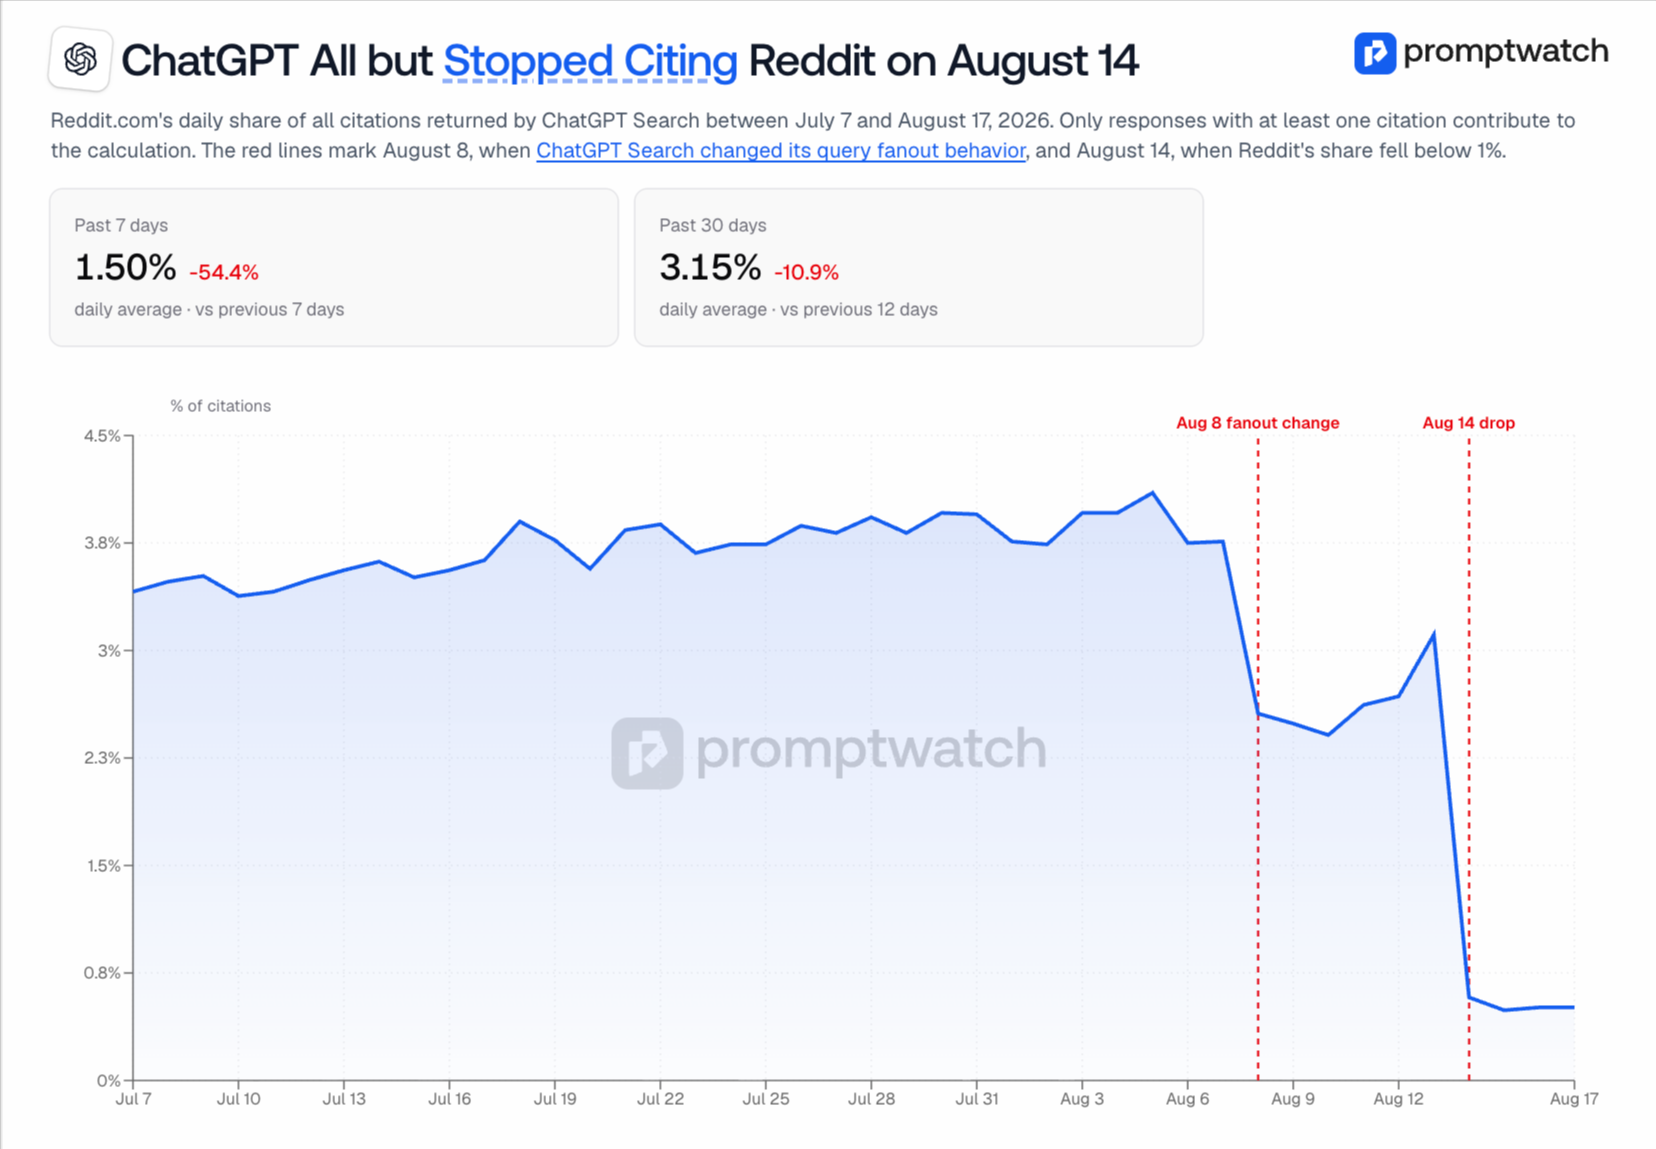
Between July 18 and August 7, 2026, Reddit’s average share of ChatGPT Search citations was 3.83%. The next time we checked (August 14) that percentage fell to less than 1% and continued to fall until it was averaging 0.52% through August 17. This represents a 86.4% decrease in reference traffic over a period of seven days.
This information came from Promptwatch, a company that tracks AI visibility and has also been reported upon by several other reputable news sources including; Semrush, Search Engine Land, Search Engine Journal, and Forbes. As a result of these reports, Reddit has publicly acknowledged this trend as well as stated that this decline will have no significant impact on their revenue stream due to the fact that traffic driven by AI referrals accounts for a very small portion of their overall traffic.
While the initial figure is factual; what does this mean for you? This is the better question and while much of the recent coverage of this issue may focus on the former question, it is certainly not the better or more relevant question.
Source: https://promptwatch.com/blog/chatgpt-stop-citing-reddit
What actually happened, and what didn’t
As evidenced by the chart above, the downward movement was in two phases. On August 8th, when Promptwatch observed a drastic change in how ChatGPT Search ran its background queries, the Reddit Citation Share percentage began to drop back down into the middle of the 2% percent range after rising to the upper end of the 3% percent range. A little more than six days later (August 14), it then took a sharp drop and fell below 1%, where it stayed at that level.
It has been widely reported that the August 8th changes were significant; Domain-Specific Background Searches, Queries run against a particular website or URL as opposed to general search, rose from approximately 0.4% to almost 17% of all Fanout queries in just one day an approximate 46X increase. However, Promptwatch explicitly stated that this does not appear to be enough to account for the larger drop off six days later. As such, the time period between these two events appears too distinct to consider as simply one causation factor. Therefore, we would also expect this to have some relevance if this decline holds up going forward. Promptwatch will continue to monitor this issue and as such is currently treating the total magnitude of this decline as provisional. Promptwatch also did not rule out the possibility that there may be a technical problem with their own data collection process.
There are two things to keep in mind here. One is that, based upon what I am seeing, it appears that this decline is primarily due to a ChatGPT specific event. This is because Google’s AI Overviews showed a decrease of 11.3% in Reddit citation counts during the same time frame and Google’s AI mode showed a decrease of 30.5%, but both declines were gradual and had no single day “cliff” drop. Two, although one week of provisional data on one platform can certainly provide evidence of a trend; we would need to observe this trend occur over a month long time frame before we could confidently say that this is a “durable” trend.
The mechanism matters more than the headline number
The most important part of the above passage, if you are working in marketing or as a growth professional, is below. Due to the increasing trend toward domain-scoped background queries (i.e., because ChatGPT will increasingly query a specific website directly rather than depending on whatever shows up in an open web search) there is a growing structural disadvantage for massive public forums such as Reddit. When a model goes straight to your domain versus querying the open web hoping to find something relevant, two conditions need to be met so you get value out of the experience. First, the model needs to have a prior belief that your domain is worth querying based upon the topical authority and/or entity clarity of your content (which we’ve detailed in our AI Discovery Framework). Second, when the model makes the direct query, your site must actually be readable; i.e. is the content accessible through the raw HTML returned to the crawler or does it depend upon JavaScript rendering? Further, is the crawler that is accessing your site (OAI-SearchBot in this case), which is primarily used to determine search cite eligibility, permitted to crawl your site at all?
This last point is frequently overlooked. There are three different crawlers: GPTBot (for collecting training data); OAI-SearchBot (to determine whether content should be included in search results); and ChatGPT User (for real-time triggered browsing). Even if a brand permits crawling for GPTBot (the bot collecting training data), they may effectively be invisible to ChatGPT Search due to blocking or rate limiting access to their site via OAI-SearchBot at the CDN layer. This misconfiguration occurs with enough frequency that it has become one of several standard checks in our Layer 1 technical audit process.
As a result of potentially more frequent direct requests from ChatGPT to domains, brands that are properly configured to handle those requests have an opportunity to gain citation share that would otherwise go to a platform such as Reddit. Brands that are not properly configured for these requests cannot take advantage of this new opportunity regardless of how good their content is.
What this doesn’t mean
This is not an indicator for you to downplay working remotely or for you to consider that reddit has lost relevance. Reasonable is reddit’s own statement that the changes have had no material impact on their operations; LLM referral traffic represents a very small portion of all reddit traffic, and reddit’s overall share of citations in google’s AI surfaces – where most user-facing ai searches occur declined by low teens (not 86%), as well.
Additionally, this does not indicate a need for you to rethink your AIO strategies based on the results of a single week of provisional numbers from one platform. As we’ve mentioned previously, and I’ll say now, citation sources are weighted differently than they were prior, will continue to be weighted differently, and therefore will require different weights at some point. Therefore, rather than rewriting strategies based upon movement, you should focus on developing systems which measure movements quickly enough.
What to check this week
- Confirm your robots.txt doesn’t block OAI-SearchBot, ChatGPT-User, or GPTBot, whether through a specific rule or an unintended wildcard Disallow, then check your CDN’s bot-management settings separately. Robots.txt is voluntary compliance. A CDN can still block or challenge these crawlers regardless of what the file says.
- Load your priority pages with JavaScript disabled and confirm the content that would actually answer a buyer’s question is present in the raw HTML.
- Check server logs for OAI-SearchBot and ChatGPT-User activity on the specific pages you most want cited. Absence of activity is itself a finding.
- Re-run your own citation rate prompt set across ChatGPT specifically this week, not on your usual monthly cadence, to see whether your own share moved during this window.
- Hold off on any changes to Reddit-specific strategy until this pattern has held for at least a month. One volatile week on one platform is not durable evidence yet.
While citation source weightings will continue to evolve with changes in web searching platforms, it’s just another reason for you to ignore them all. But it’s also why we layered measurement into our framework so you can track your way through it. And those brands that are able to take advantage of what’s happening right now because they have the resources and positioning to do so aren’t going to be the ones trying to figure out what to do about the moment, but rather the ones who have been set up to receive the direct ask.
Kaushal Thakkar
Founder & CEO, Infidigit